
 Tech & AI
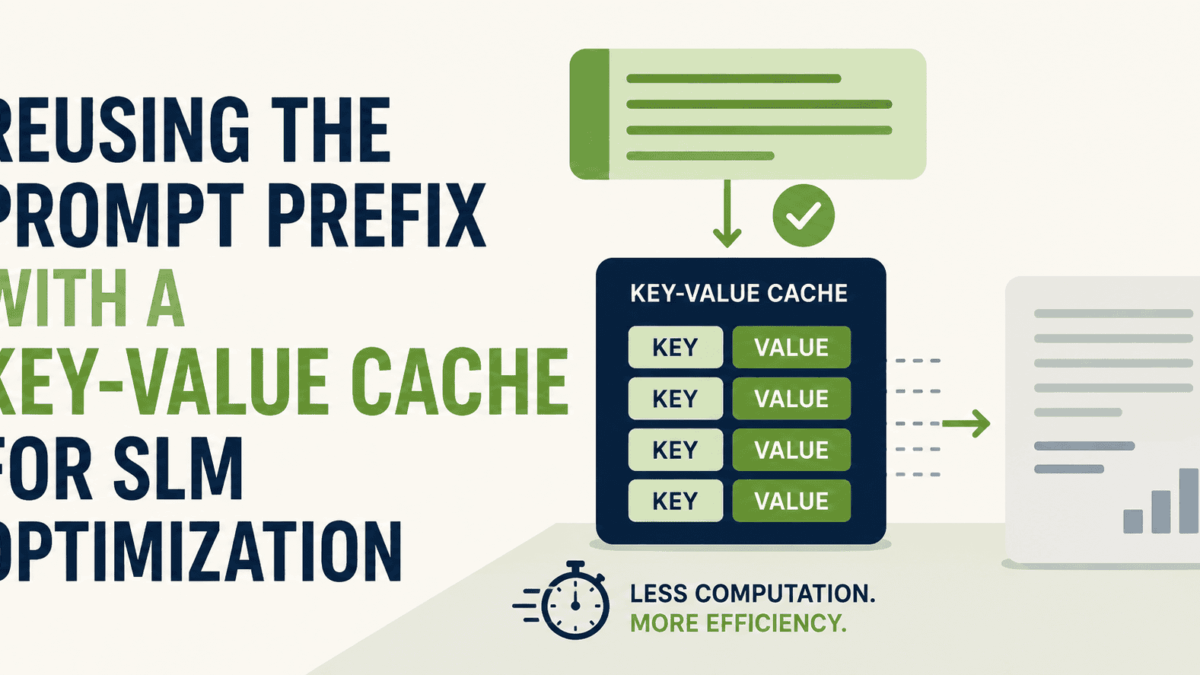
Small language models (SLMs) are increasingly attractive for on-device and low-latency applications, but their performance still depends heavily on how efficiently inference is managed. One effective optimization is reusing the prompt prefix with a key-value (KV) cache, a technique explored in the second part of our series on SLM optimization. When an SLM generates text, it processes the entire prompt token by token. For each token, the model computes keys and values that are later used in the attention mechanism. Without caching, every new request repeats these computations for the same prefix, wasting time and compute resources. A KV cache stores those intermediate keys and values, so they can be reused across calls instead of recalculated. The core idea is straightforward: if multiple prompts share the same beginning—such as a fixed system instruction or a common context—the model can compute the KV pairs for that shared prefix once and then reuse them for subsequent requests. This avoids redundant work and shortens the time to first token, which is especially valuable in interactive or real-time scenarios.
Implementing prefix reuse with a KV cache requires careful design. The cache must be keyed to the exact prefix, and any change in the prompt invalidates the stored entries. Memory management is also important: caches grow with context length, so strategies like eviction or quantization may be needed to keep them practical. Despite these considerations, the gains can be significant. By skipping repeated prefix computations, SLMs can serve more requests with the same hardware and deliver faster responses. This technique fits naturally into a broader optimization toolkit. Combined with other methods such as quantization or pruning, KV cache reuse helps make small language models more viable for edge deployment and cost-sensitive production systems. The key takeaway is simple: don’t recompute what you can reuse.